



Built for the workloads that matter most.
Reserve AI compute capacity in Europe for long-term growth. Gain dedicated access with the scale, continuity, and control to execute your AI strategy.
Mistral Compute
Timeline
Zero to cloud in under a year.

Capacity
1
GW
Sovereign AI capacity across the EU by 2030.
Latest-generation infrastructure
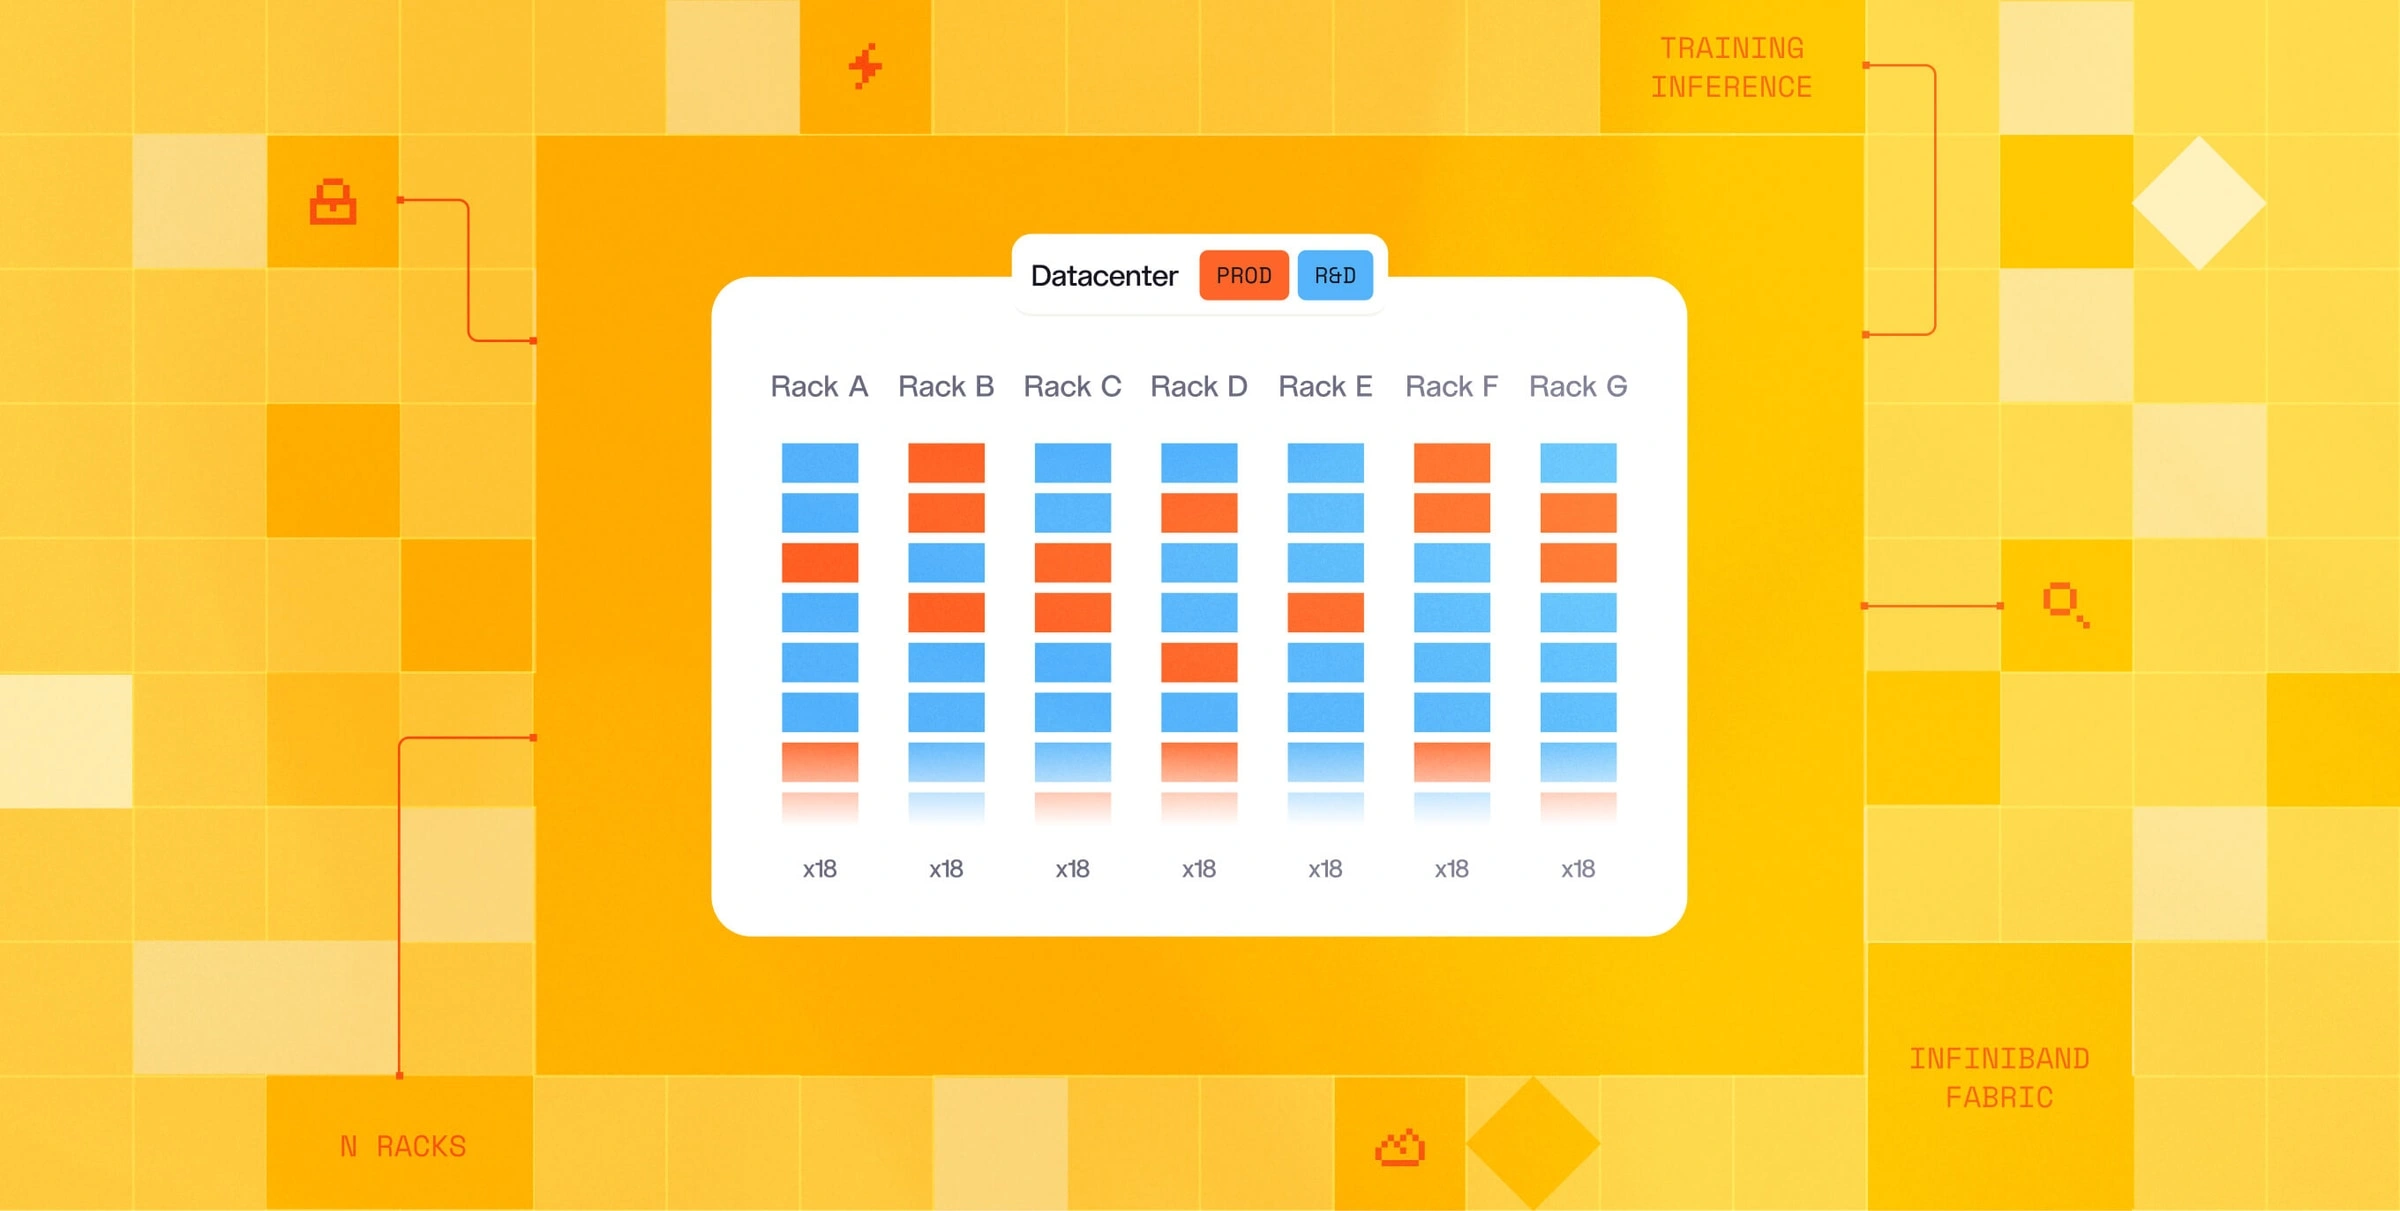
GB200, GB300 and B300 GPUs, with Grace and x86 CPUs for the most demanding AI workloads.
Frontier-grade compute for the most demanding AI workloads.
The infrastructure that powers Mistral’s frontier models, now yours.
Use high-performance GPU infrastructure without sourcing the hardware, building the environment or operating it yourself.
Schedule and run large-scale training and HPC workloads without setting up or operating the cluster yourself.
Deploy and scale containerized AI workloads without managing the Kubernetes control plane or underlying infrastructure.
Host, manage, and serve production AI systems with regional controls, deep observability, and enterprise identity management.
Control at every layer.

Observability.
Dashboards, logs, and metrics built in. Zero extra cost. GPU health, power, thermals, ECC, throughput. Per-job telemetry, streamed to the tools you already run.

Governance.
SSO and SCIM out of the box. RBAC maps to SLURM accounts. Secrets, key management, audit trails, CI/CD webhooks.

Reliability.
Enterprise-grade SLAs across training and inference, with dedicated incident response.

Support.
Infrastructure and AI specialists on every tier, with direct escalation to the engineering team behind the platform. Auto-healing is instrumented by our own models.

Security.
Purpose-built security for large-scale AI workloads: EVPN-VXLAN network isolation, AES-256 encryption at rest with BYOK, and defined data wiping protocol.